Short answers to what readers ask most about this topic.
01Why should an agent stage content instead of editing files directly?
Because a single content item can touch several coupled files, and a partial edit is a silent production bug. Staging turns the agent's output into a proposal that one deterministic script validates in full — key trees, metadata, assets — before it writes anything into the repository.
02What is the most common mistake in agent-written bilingual content?
Key-tree drift: an extra bullet point or a renamed section written in one language and not the other. It does not fail loudly, it just breaks one locale of one page in production, which is why equality of the two key trees should be a hard check rather than a review item.
03Is a validate-then-write script automatically safe?
Only if validation covers everything that can fail during the write. A script here validated all the content correctly, then failed partway through writing because a constant it inserts after had moved to another module — leaving the repo half-merged. Anchor resolution and path existence belong in the validation phase.
04How should in-article images be credited at scale?
Fetch them with a script that reads the author and licence from the source API rather than typing them by hand, then store the result in one typed registry that the article components spread into a figure component. One image reused by three posts then carries one attribution that can be corrected in a single place.
05What is the model good and bad at in a content pipeline?
Good at structure, consistency of house style, and producing a natural second language. Bad at knowing what is true and at restraint — every specification number needs a source, and a fixed section skeleton per post type prevents the fifth section that repeats the second.
Claude Code Content Pipeline for a Bilingual Next.js Blog
How a 470-post bilingual blog is generated with Claude Code: a staging folder, a validate-then-write merge script, parity guards, and the day it half-merged.
Publishing a bilingual post here touches five coupled files, so the agent never edits them directly: it writes a staging folder, and one script validates key-tree parity, translation coverage and metadata before writing anything. The guard rails, not the writing, are what make agent-generated content safe to ship.
This site has several hundred articles, each existing twice — once in English and once in Indonesian — with the same key tree, the same components and the same structured data. That is a content problem that looks like a writing problem and is actually a consistency problem, and consistency is exactly where a language model is weakest and a script is strongest.
So the pipeline is built around a division of labour: the agent writes prose and picks structure, and deterministic scripts decide whether that output is allowed into the repository. Here is how it works, including the failure it hit today.
Why a post is five files, not one
A single published article is spread across the codebase because different parts of the framework need different pieces of it.
A React component holds the structure — headings, tables, code blocks, callouts — and reads every sentence through a translation key.
Two message files hold the prose, one per locale, and their key trees must match exactly or the missing locale throws at runtime.
A registry entry holds the card data: slug, category, cover, date, read time.
A metadata entry holds SEO title, description, keywords and dates, and the route file maps the slug to a dynamically imported component.
Editing five files by hand for one post is tedious; editing them for twenty is a guarantee of drift. The mismatch does not fail loudly either — a missing key breaks one locale of one post in production, which is the kind of bug that survives for months.
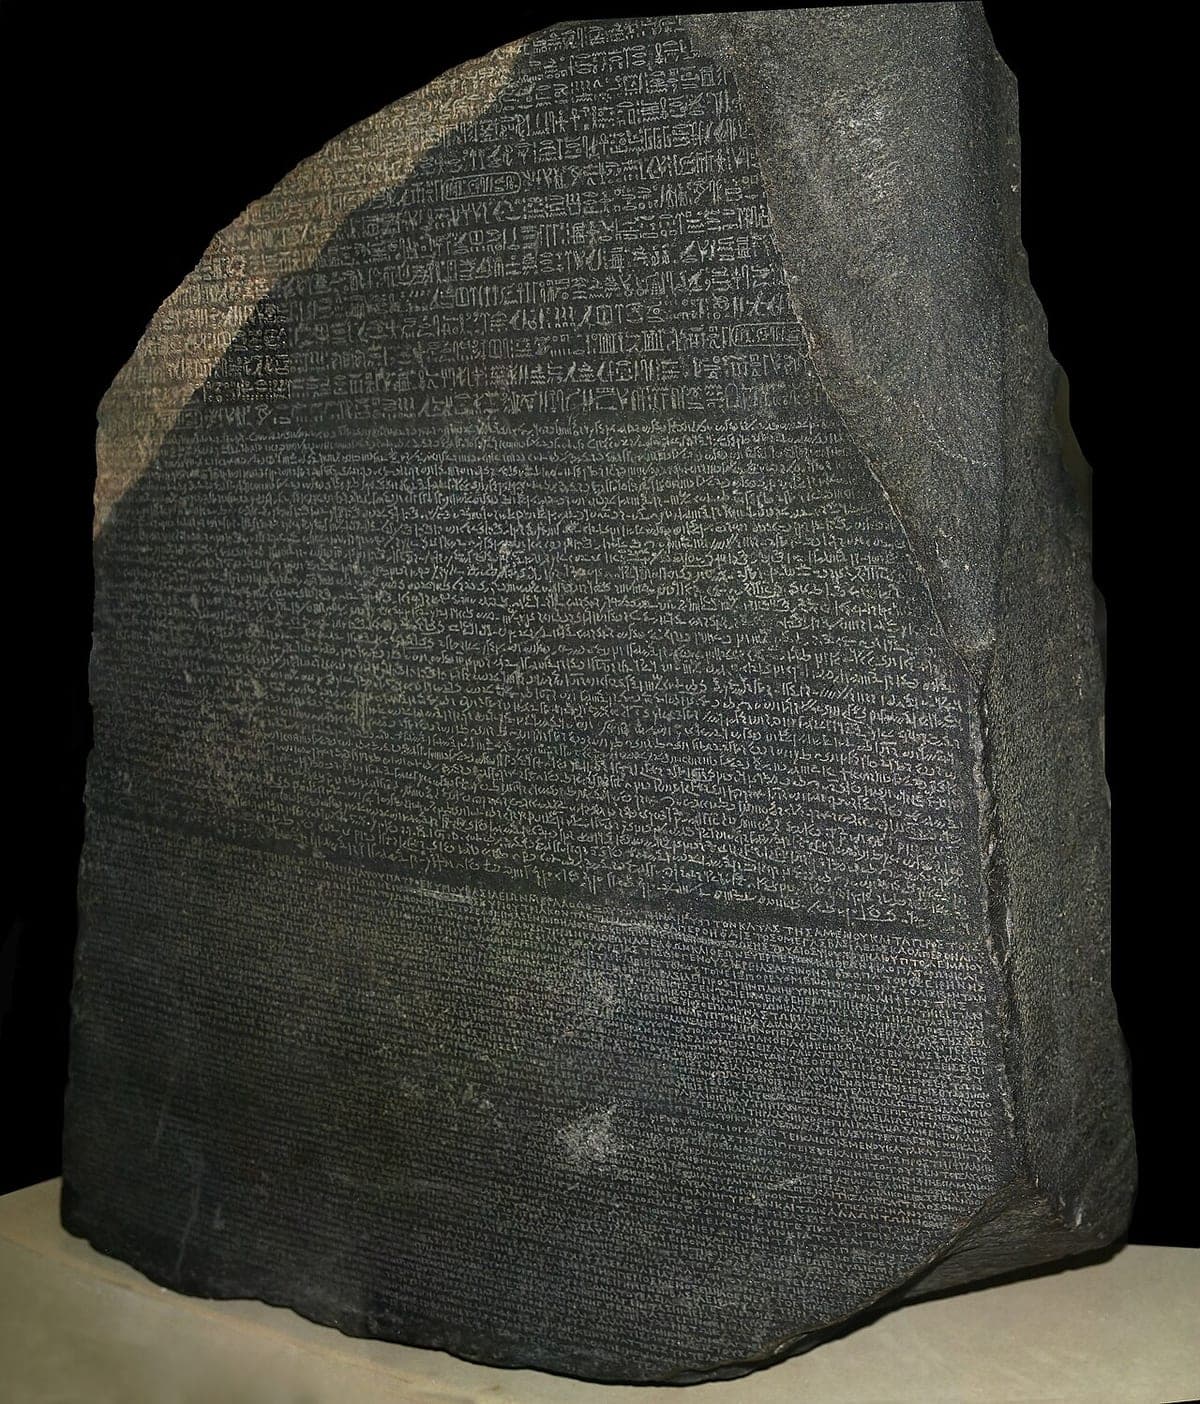
The oldest known parity problem: one message, several scripts, and a reader who can only verify the version they can read. A bilingual site has the same failure mode, which is why key-tree equality is enforced by a script rather than by attention. Photo: Hans Hillewaert / Wikimedia Commons, CC BY-SA 4.0
Stage, validate, then write
The rule that makes the whole thing safe is that the agent produces a proposal, not an edit. Everything lands in a staging directory, and a merge script is the only thing allowed to touch the repository.
# The agent never edits the five coupled files by hand. It stages, then
# one script validates everything and only then writes anything.

/tmp/blog-staging/agent-a/
  registry.json   # slug, category, dates, cover, SEO title and description
  en.json         # the English fragment, keyed by translationKey
  id.json         # the Indonesian fragment, same key tree
  faqs.json       # five bilingual question and answer pairs

node scripts/merge-blog-staging.mjs   # validates, then edits 5 repo files
node scripts/merge-blog-faqs.mjs      # adds FAQPage schema data
npx tsc --noEmit && npm run build     # parity guard runs inside the build
The script checks a specific list before it writes a byte: unique slug and translation key, a valid category and month, a real date, the cover file existing on disk, the component file existing, the two locale key trees being identical, no characters that would break the message format, and complete metadata. Only then does it edit the five files.
The guards that have actually caught something
Every check in that list exists because something went wrong once. The five that earn their place most often are these.
Key-tree equality between locales. This is the single most common agent mistake — an extra bullet point written in one language and not the other.
Component-reads-only-existing-keys. Catches a renamed section heading that leaves a dangling translation call.
Unsafe characters in translated strings. Braces and angle brackets belong in the component, not in the prose, and a stray one turns into a runtime formatting error.
A build-time parity assertion between the post registry and the metadata registry, so a post can never ship registered but undocumented.
A required key-takeaway paragraph on every post, which exists for answer engines but doubles as a check that the agent understood the article it just wrote.
None of these are clever. They are all cheap, mechanical, and they turn a class of silent production bug into a script that refuses to run.
Make the validator runnable against already-published posts too, not just staged ones. Retrofits bypass the staging path entirely, and a hand-edited translation is exactly where key-tree drift creeps back in.
The day the pipeline half-merged
Writing this article, the merge script failed in the most instructive way possible: it validated everything correctly, began writing, and then threw partway through.
Error: anchor not found in lib/blog-posts-static.ts:
  export const REAL_IMAGE_SLUGS = new Set([

# What had happened: the constant moved to lib/blog-display.ts months ago.
# The merge script validated the staged content perfectly, started writing,
# updated messages/en.json, messages/id.json and the post registry, and
# THEN failed on an anchor it could no longer find.

# The repo was left half-merged: translations present, metadata missing.
# Re-running would not help either, because the script skips slugs that
# already exist in en.json — it considered the work done.
The cause was an anchor. The script inserts new entries after known lines of code, and one of those constants had moved to a different module some time ago. Because anchors are resolved at write time rather than during validation, the script had already updated both message files and the post registry before it discovered it could not find the third target. Worse, re-running was not a recovery path: the script skips slugs it finds already present in the English messages, so it considered the job done.
A validate-then-write script is only atomic if validation covers everything that can fail during the write. Anchor resolution, file permissions and path existence all belong in the validation phase — otherwise you have a script that is careful about your data and careless about its own preconditions.
Images and covers are scripts, not judgement calls
The same principle extends to assets. Cover images are generated from the site's own template, so they are always the right dimensions, always on-brand, and never a stock photo whose licence nobody checked. In-article images are downloaded from Wikimedia Commons by a script that reads the author and licence from the API and writes them into a typed registry.
# Covers are generated from the site's own template, not downloaded.
node scripts/generate-blog-cover.mjs --manifest covers.json

# In-article images are fetched from Wikimedia Commons, re-encoded, and
# their author and licence are read from the API rather than typed by hand.
node scripts/fetch-blog-inline-images.mjs \
  --manifest images.json --report report.json

# The report becomes a typed registry, so one image reused by three posts
# carries exactly one credit line that can be corrected in one place.
export const BLOG_FIGURES: Record<string, BlogFigureSource> = { ... };
That registry is the part I would recommend to anyone doing this. Because credits live in one file rather than being retyped in each article, an image reused by three posts carries one attribution string, and correcting a wrong one is a single edit instead of a search across the catalogue.
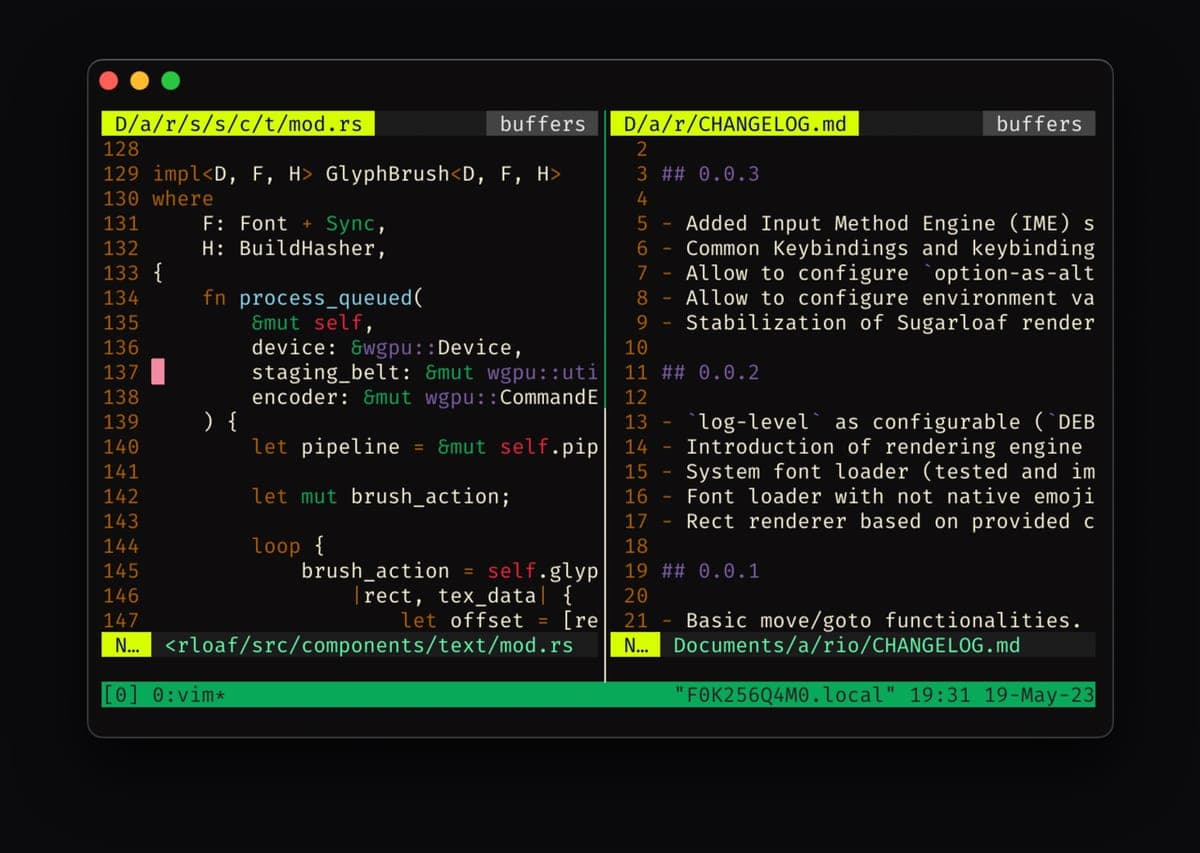
What the loop actually looks like: a staging build in one pane, the merge script in another, typecheck and build in a third. The agent writes; these three panes decide whether any of it survives. Screenshot: Avelino0 / Wikimedia Commons, CC BY-SA 4.0
What the agent is good at, and what it is not
After a few hundred posts through this pipeline, the division is clear and slightly counter-intuitive.
Good at structure. Given a topic and a house style, the sectioning, tables and code examples come out consistent and sensible.
Good at the second language, with a caveat: the Indonesian reads naturally, but technical terms need a house glossary or it will drift between translating and transliterating them.
Weak at knowing what is true. Every specification number, command flag and product claim needs a source, which is why the pipeline treats a citation list as mandatory rather than decorative.
Weak at restraint. Left alone it will happily write a fifth section that repeats the second, so a fixed skeleton per post type is worth more than any prompt about brevity.
The honest summary is that the model is a strong drafter and an unreliable fact-checker, so the harness has to supply the facts and verify the shape.
Building your own version
If you maintain content in a repository, four steps get you most of this.
List every file a single content item touches. If the answer is more than two, the agent should stage rather than edit.
Write one script that validates the staged item completely and writes only if everything passes — including its own preconditions.
Put the invariants that matter into the build, not into a checklist. A parity assertion that fails the build is worth ten paragraphs of instructions.
Automate assets the same way. Generated covers and script-fetched, attributed images remove two whole categories of mistake.
The interesting part of agent-generated content is not the writing, which is the easy half. It is building a harness strict enough that a confident, fluent, occasionally wrong writer cannot break production — and then keeping that harness honest, including on the day it discovers a bug in itself.