Load Testing & Site Reliability Engineering for a German Logistics Platform
What the framework found
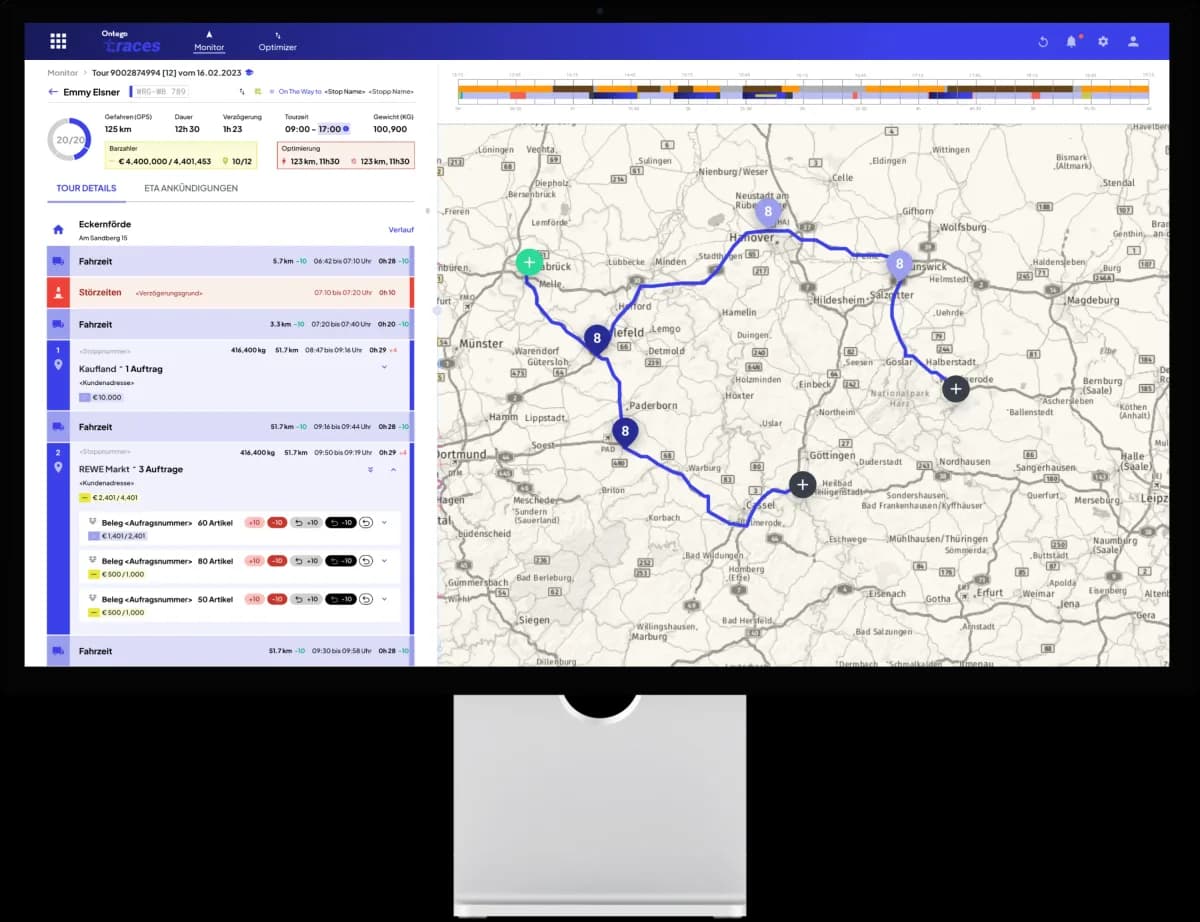
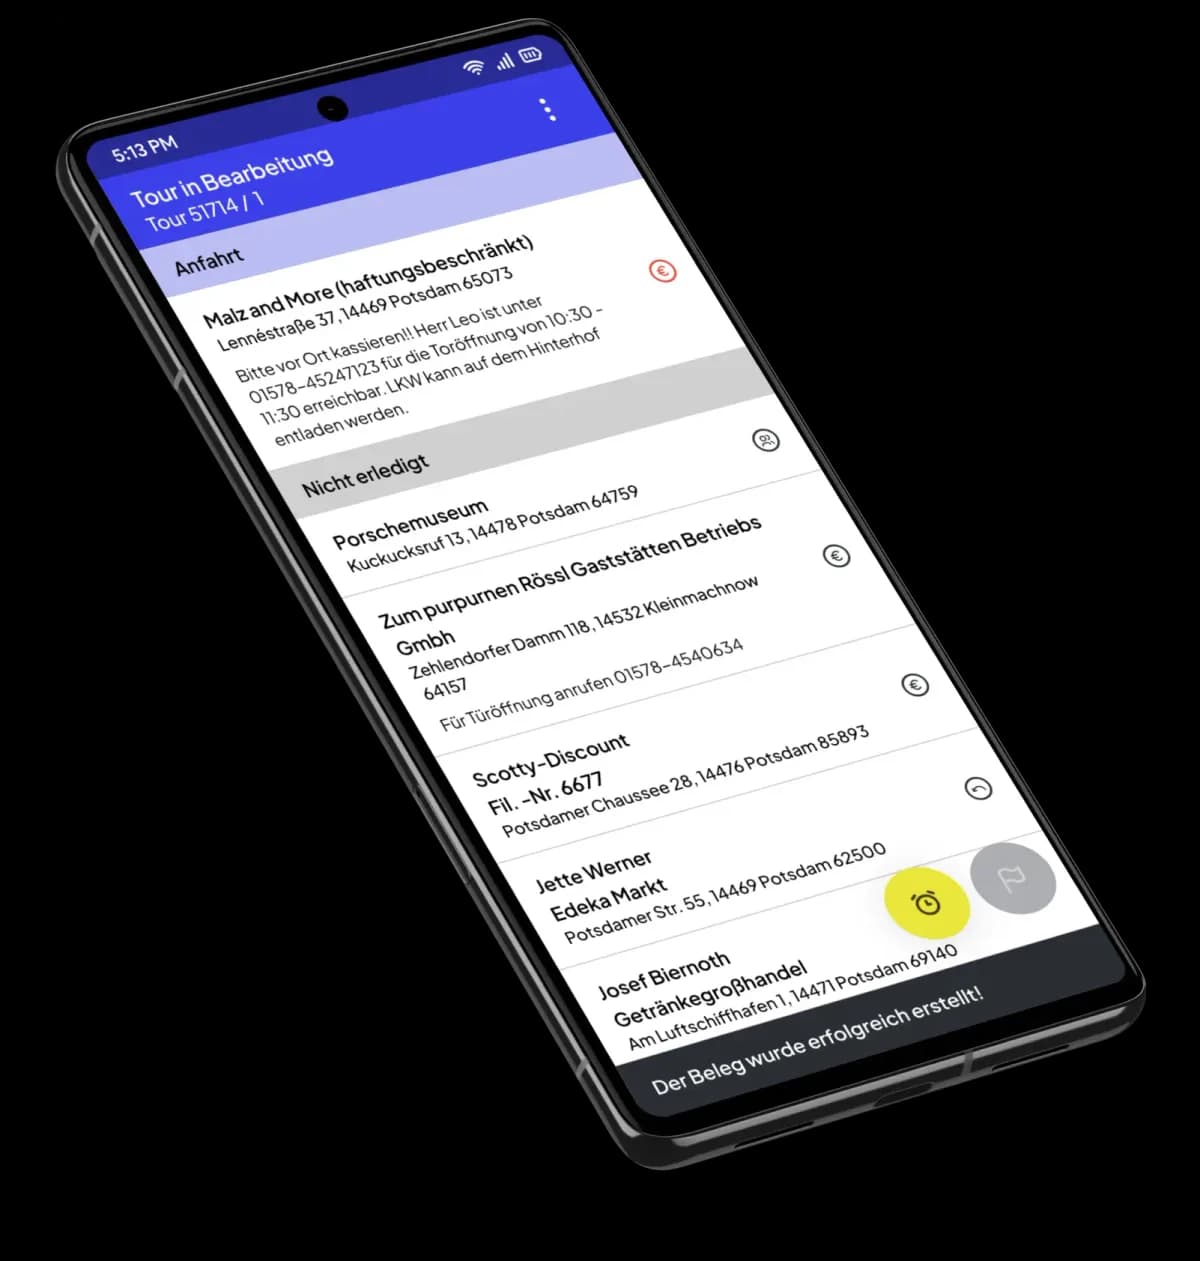
Ontego Traces is a logistics platform used by German delivery operators. My thesis gave it its first instrumented performance baseline — an SRE-aligned benchmarking framework, and ten controlled experiments against its highest-volume write path — to find where it actually breaks under load, and prove which fixes matter.
Ten experiments, one verdict
Each bar is a real k6 run under identical load, shown relative to the untuned baseline. The tuned single replica wins both metrics — beating the two-replica configurations it was supposed to lose to.
Relative throughput
Longer is betterRelative tail latency
Shorter is betterThe instinct is to scale out. But tuning the database on one replica delivered more throughput and lower latency than adding a second — because the real bottleneck was never CPU.
The ceiling I found
A live pg_stat_activity trace revealed the hard limit: every write request contends for the same shared configuration row, serialising all concurrent writes. It's the last rung of the bottleneck ladder — an application-level fix, not an infrastructure one.
What I learned
Measure before you scale
Adding a second replica improved tail latency but lifted throughput by under 10%. Horizontal scaling only pays off when CPU is the constraint — and here it wasn't.
The database is the ceiling
Disabling synchronous commit, enlarging the page cache and widening the connection pool beat two-replica scaling on every metric — from a single machine.
Some infra problems are app bugs
A live database trace exposed a single shared row serialising every write. No replica count or connection proxy can remove a row-level lock — only an application change can.
You can't tune what you can't see
With the four SRE golden signals on one Grafana axis, a latency spike stopped being something to interpret afterwards and became something to read live — pointing straight at the layer that was actually saturated.
What I shipped
SRE benchmarking framework
Reproducible k6 experiments with a fixed, staged methodology — the platform's first instrumented performance baseline.
CPU-based autoscaler
A Docker Swarm daemon that scales the busiest service between one and three replicas on CPU and queue-depth signals, with cooldown.
Observability stack
Prometheus + Grafana capturing all four golden signals, federated across two VMs so app metrics survive under load.
CI/CD quality gate
A pipeline check that blocks production deploys when tail latency or error rate breach an agreed threshold.