
Key Takeaway
An AI agent is excellent at gathering incident evidence in parallel and dangerous at acting on a guess. The safe pattern is read-only investigation with a PreToolUse hook blocking destructive commands, testing the origin directly rather than through a CDN, and requiring a stated hypothesis before any change.
The site was up, the deploy had reported success, and the page in the browser was two versions old. Nothing in the application logs was wrong, because nothing in the application was wrong. That incident took twenty minutes to resolve with an agent and would have taken me an hour alone, but it also showed me exactly where letting an agent loose on a production box goes badly.
This is the working method I settled on: what an agent should do during an incident, what it must be prevented from doing, and the evidence order that keeps both of us honest.
Where an agent genuinely helps
Incident response is mostly evidence gathering under time pressure, which is a good match for something that can run ten commands while you think about the eleventh.
- Breadth. It will check the container, the port binding, the process table, the disk and the certificate expiry in the time it takes you to remember the third of those.
- Recall. It reads the deploy workflow, the reverse proxy config and the compose file together, which is where the contradiction usually lives.
- Narration. Asked to state a hypothesis before acting, it produces a written trail that becomes the postmortem for free.
What it is bad at is knowing when it is wrong. A confident wrong hypothesis plus shell access is how a small incident becomes a large one, which is why the guard rails below are not optional.
Rule one: stop asking the CDN
If a site sits behind a CDN or a caching proxy, the first thing to establish is which layer is answering. A response from the edge tells you what the edge remembers, not what the application currently does, and hours get lost debugging code that is already correct.
# Rule one of debugging a site behind a CDN: stop asking the CDN.
curl -sI https://www.example.com/ | head -20            # what the world sees
curl -sI --resolve www.example.com:443:127.0.0.1 \
     https://www.example.com/ | head -20                 # what the origin says

# If those disagree, the bug is in the cache layer and no amount of
# reading application code will find it.

# Same discipline for the redirect chain, which hides a surprising
# number of "the site is down" reports.
curl -sIL http://example.com/ | grep -E '^(HTTP|location:)'
The same discipline applies to the redirect chain and to hostnames. A rule that sends the bare domain to the www host, or an application that only listens on one of them, produces symptoms that look like an outage and are actually configuration. Following the chain explicitly turns a mystery into one line of output.
Write the origin-versus-edge comparison into your runbook as the literal first step, with the exact commands. During an incident nobody invents good diagnostics; they run whatever they can remember, and what they remember is whatever is written down.
The incident: a deploy that succeeded and changed nothing
Here is the case that taught me the most, reconstructed from the commands that actually mattered. The application was containerised, the deploy pipeline was green, and the served content was stale.
# The incident: a deploy "succeeded", the site kept serving old content.
# The evidence that mattered, in the order it was gathered:

docker compose ps                    # container up, restarts: 0
docker compose logs --tail=100 web   # no errors, no recent boot line
ss -tlnp | grep :3000                # PID owning the port is the OLD process
curl -s localhost:3000/ | grep -o 'build-[a-z0-9]*'   # old build id

# Root cause: the new process failed to bind because the previous one had
# never exited. The deploy script only checked that its own command
# returned zero, so it reported success while nothing had changed.
The lesson generalises well beyond this stack. A deploy script that checks only its own exit code is measuring the wrong thing: what matters is whether the running process is the new one. Since then, every deploy of mine ends by asserting that a build identifier served over HTTP matches the one just built — a two-line check that would have turned this incident into a failed pipeline.
Never let an agent restart, prune or redeploy as its first action during an incident. Restarting destroys the evidence that explains the failure, and half the time it also appears to fix the problem, which guarantees the same incident returns next week with no diagnostic trail.
Four evidence habits worth enforcing
These are the instructions I keep in the project's memory file so they apply to every incident session without being retyped.
- State a hypothesis before running anything that changes state, and name the observation that would disprove it.
- Capture before mutating. Copy the logs, the process list and the config to a scratch directory first, because the next command may erase them.
- Verify at the layer you suspect, not the layer that is convenient. Curl the origin, query the database directly, read the file on the server rather than in the repository.
- Distrust tooling that mediates. A wrapper that rewrites commands, or a local checkout that looks like the remote one, can silently report the wrong system's state — a mistake I have made and now check for explicitly.
That last habit is worth spelling out because it produced a false conclusion for me once: output that appeared to describe a remote repository was in fact describing the local one, and I believed a merge had happened that had not.
Hooks are the real safety mechanism
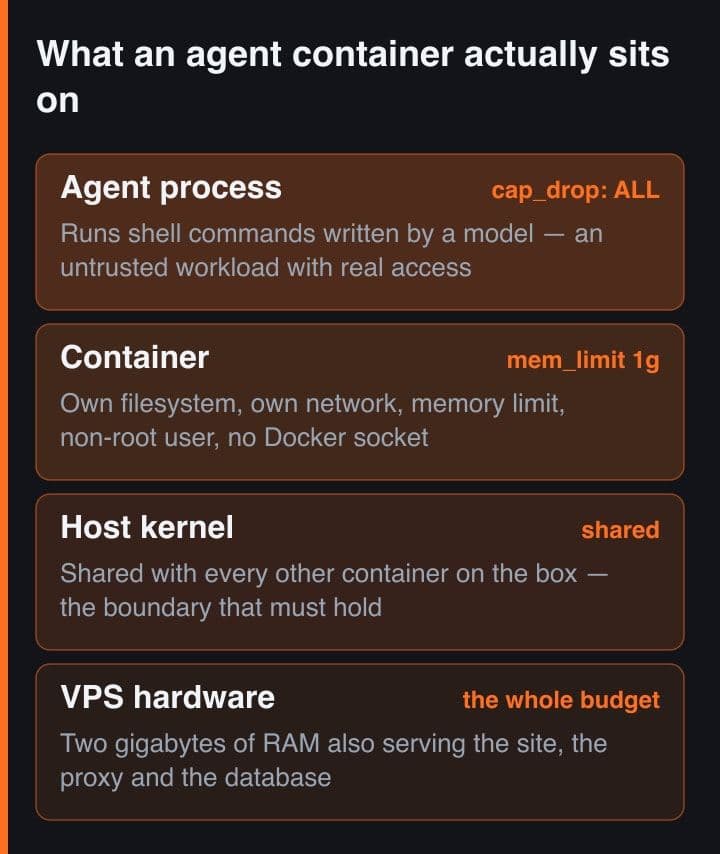
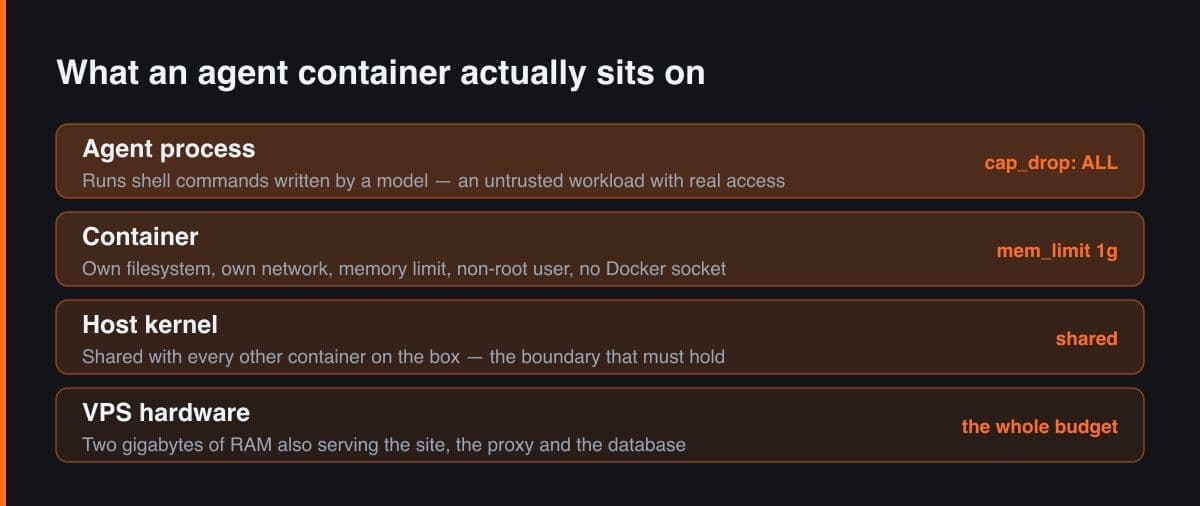
Permission prompts protect you when you are reading them. During an incident nobody reads them, which is exactly when you want a rule that cannot be talked out of. A PreToolUse hook that inspects the command and denies a short list of irreversible operations is the cheapest insurance available.
// A PreToolUse hook is the difference between an assistant that can
// investigate production and one that can break it. This one refuses
// the small set of commands nobody should run during an incident.
#!/bin/bash
input=$(cat)
cmd=$(echo "$input" | jq -r '.tool_input.command')

if echo "$cmd" | grep -Eq 'rm -rf /|docker system prune|DROP TABLE|truncate '; then
  echo '{"hookSpecificOutput":{"hookEventName":"PreToolUse",
    "permissionDecision":"deny",
    "permissionDecisionReason":"destructive command blocked during incident"}}'
  exit 0
fi
echo '{}'
Pair it with a permission mode chosen deliberately for the session. Investigation runs read-only; the moment a fix is agreed, that is a separate, narrower session with the change reviewed by a human before it runs. Mixing investigation and remediation in one loose session is the setup for the second incident.
The incident loop that works
Six steps, in this order, every time.
- Establish the symptom precisely, from outside the system: what URL, what response, what time it started.
- Compare edge and origin. If they differ, stop and work on the cache layer.
- Confirm what is actually running: image, build identifier, process, port owner.
- Read the three configs that define the path — proxy, container, application — together rather than one at a time.
- State the hypothesis, make the smallest change that tests it, verify at the origin.
- Write the finding down before the adrenaline fades, then encode it as a check.
Step six is the one that compounds. Nearly every incident I have had twice was one where the first occurrence produced a fix and no check, and a fix without a check is a memory that expires.
Turning findings into guard rails
The output of an incident should be at least one automated assertion, not only a paragraph. A stale-deploy incident becomes a post-deploy build identifier check. A caching incident becomes a synthetic request that bypasses the edge. A disk-full incident becomes an alert threshold that fires before the service does.
This is also where an agent earns its place after the incident rather than during it: writing the check, the alert and the runbook entry is exactly the tedious, well-specified work it does reliably, at a moment when you are too tired to do it well yourself.
An AI agent shortens the evidence-gathering half of an incident dramatically and adds risk to the acting half. Keep those halves separate — read-only investigation with destructive commands blocked, then a deliberate, reviewed change — and you get the speed without buying a second outage.